課程名稱:GARP Risk and AI (RAI) 國際認可證書課程 (1 科 AI 風險管理)
- 簡稱:GARP RAI Training Course |
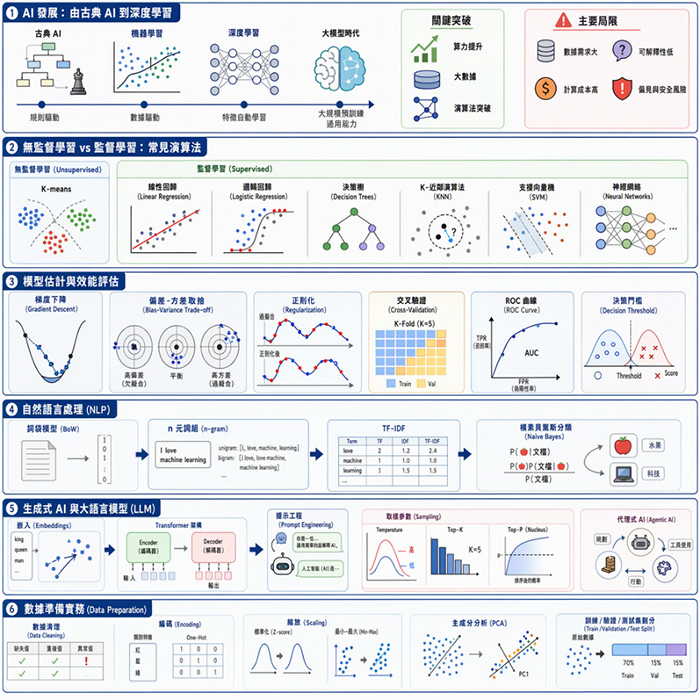
1. AI and Risk: Introduction and Overview
1.1 Central principles of Classical AI, including search methods and recursion.
1.2 Limitations of classical AI.
1.2.1 Frame problem and classical AI limits
1.2.2 Brittleness of rule-based systems
1.3 Potential and limitations of deep learning.
1.4 Identify key breakthroughs leading to advances in AI and ML.
1.4.1 Key breakthroughs in AI and ML
1.5 Compare and contrast reinforcement, supervised, unsupervised, and semi-supervised learning, and identify practical applications for each technique.
1.5.1 Choosing supervised learning approaches
1.6 Risks associated with inscrutability in AI and ML.
1.7 Risks associated with over-reliance on AI systems.
1.8 Ways in which AI exposes individuals, organizations, and society to risk.
1.8.1 Data governance and model risk
1.8.2 Model review framework considerations
1.8.3 AI risks to society and organizations
2. Tools and Techniques
2.1 Differentiate between machine-learning techniques and classical econometrics.
2.1.1 Econometric assumptions versus machine learning
2.2 Differentiate among unsupervised, supervised, semi-supervised, and reinforcement learning models.
2.2.1 Reinforcement learning and recursive search
2.3 Distinguish between different data types.
2.4 How to encode categorical variables.
2.5 How to clean data and the reasons for data cleaning.
2.6 Data preparation techniques and their benefits.
2.6.1 Resampling to balance class data
2.7 Apply data scaling and data transformation to a set of data.
2.7.1 Data transformation for skewed variables
2.7.2 Outlier detection with data scaling
2.8 How principal components analysis (PCA) is used to reduce the dimensionality of a data set.
2.8.1 PCA for dimensionality reduction in yields
2.9 The differences between the training, validation, and test data sub-samples, and how each is used.
3. Unsupervised Learning
3.1 Differentiate between clustering techniques.
3.2 Illustrate how the K-means algorithm separates data into clusters.
3.2.1 K-means distance to cluster centroids
3.3 The advantages and disadvantages of K-means clustering.
3.4 Performance measures such as Within-Cluster Sum of Squares (WCSS) and Between-Clusters Sum of Squares (BCSS).
3.4.1 Cluster compactness performance measures
3.5 Apply different methods to determine the optimal number of clusters in unsupervised learning.
3.6 The construction and uses of a dendrogram.
4. Supervised Learning – Econometric Techniques
4.1 Identify the uses and limitations of simple and multiple linear regression.
4.2 Interpret the results of the simple and multiple linear regression.
4.2.1 Interpreting regression model output ranges
4.3 Common misspecification problems with linear regression models and potential remedies.
4.3.1 Nonlinearity and polynomial misspecification remedies
4.4 How logistic regression can be applied to solve classification problems.
4.4.1 Handling unbalanced classes in logistic regression
4.4.2 Ordered logistic regression properties
4.5 Explain the use of linear discriminant analysis for classification tasks.
5. Supervised Learning – Machine Learning Techniques
5.1 Differentiate between the two types of decision trees and illustrate how each is constructed and interpreted.
5.1.1 CART splitting for target variables
5.2 How pruning and ensemble techniques can be used to enhance the performance of decision trees.
5.2.1 Benefits of ensemble methods
5.2.2 Ensemble techniques to reduce overfitting
5.3 Apply the K-nearest Neighbors (KNN) method for classification.
5.3.1 Feature scaling in KNN classification
5.3.2 Choosing supervised models for ordinal ratings
5.4 Illustrate how support vector machines are used to classify data.
5.5 How neural networks are constructed and discuss associated challenges.
5.5.1 Fairness and bias in neural networks
5.5.2 Deep neural network privacy and bias concerns
5.5.3 Advancements enabling complex function learning
5.6 Advanced neural network structures including convolutional neural networks (CNNs) and recurrent neural networks (RNNs).
5.6.1 Convolutional networks for local image features
5.7 Describe how autoencoders are used for dimensionality reduction and differentiate between autoencoders and PCA.
5.7.1 Deep learning representations and dimensionality reduction
6. Semi-Supervised Learning
6.1 How semi-supervised learning differs from unsupervised and supervised learning.
6.2 Assumptions required for effective semi-supervised learning.
6.3 Identify the applications of semi-supervised learning.
6.4 Differentiate between transductive and inductive semi-supervised learning techniques.
6.5 Compare and contrast self-training and co-training methods of semi-supervised learning, understanding their respective strengths and weaknesses.
6.5.1 Co-training to mitigate overfitting
7. Reinforcement Learning
7.1 Explain key principles and frameworks behind reinforcement learning.
7.1.1 When reinforcement learning is appropriate
7.1.2 Model free reinforcement learning principles
7.1.3 State value in reinforcement learning
7.2 Compare and contrast exploration, exploitation, and ε-greedy strategies.
7.2.1 Balancing exploration and exploitation
7.2.2 Epsilon greedy exploration parameter
7.3 Reinforcement learning in the context of the Multi Armed Bandit (MAB) problem.
7.3.1 Multi-armed bandit resource allocation
7.3.2 Multi-armed bandit experiment sequencing
7.4 Differentiate between the Monte Carlo and Temporal Difference methods.
7.4.1 Temporal difference value updates
7.4.2 Monte Carlo with continuing tasks
7.5 Deep reinforcement learning.
7.6 Compare and contrast value-based and policy-based reinforcement learning methods.
8. Supervised Learning – Model Estimation
8.1 Compare and contrast the Ordinary Least Squares (OLS), Nonlinear Least Squares (NLS), and Maximum Likelihood Estimation (MLE) methods.
8.1.1 Comparing estimation methods for nonlinear models
8.2 How gradient descent method is used for estimating model parameters.
8.3 How batch and stochastic gradient descent and dynamic learning rate techniques are used for improving convergence.
8.4 How backpropagation is used to determine the optimal weights in neural networks.
8.5 Understand the computational issues when training neural networks and solutions to these issues.
8.6 Underfitting and overfitting and explain their causes.
8.6.1 Overfitting and underfitting in neural networks
8.6.2 Overfitting causes and regime changes
8.7 The tradeoff between a model's bias and its variance.
8.7.1 Bias and variance tradeoff in prediction
8.8 The tradeoff between a model's prediction accuracy and interpretability.
8.8.1 Model accuracy versus interpretability tradeoff
8.9 The use of regularization techniques to prevent overfitting.
8.10 Cross-validation, stratified cross-validation, and bootstrapping techniques.
8.10.1 Cross-validation and model performance ranking
8.11 How grid search method can be used for tuning hyperparameters.
8.11.1 Grid search for hyperparameter tuning
9. Supervised Learning – Model Performance Evaluation
9.1 The metrics used to evaluate the performance of a supervised learning model.
9.1.1 Generative AI report evaluation metrics
9.2 Evaluate the performance of continuous-outcome and classification models using a range of metrics.
9.2.1 Multi-class classification evaluation methods
9.2.2 Error sensitivity in continuous outcome metrics
9.2.3 Single point estimate reliability in decisions
9.2.4 AUC interpretation below random classification
9.2.5 Precision calculation from confusion matrix
9.3 The relationship between true and false positive rates and how this trade off can be illustrated using the receiver operating curve (ROC).
9.3.1 ROC curve false alarm rate estimation
9.3.2 Threshold reduction true positive impact
9.4 The selection of decision thresholds for classification models based on business needs.
9.4.1 Fairness threshold decisions across demographic groups
9.4.2 Fraud detection threshold business trade-offs
9.4.3 Demographic parity in loan approval rates
9.4.4 Predictive parity qualified applicant proportions
10. Natural Language Processing
10.1 Applications of natural language processing (NLP).
10.1.1 NLP applications in service routing
10.2 Pre-processing steps for NLP.
10.2.1 Stemming and lemmatization pre-processing
10.3 The bag of words (BoW) and n-grams approaches.
10.3.1 Bag of words with L2 normalization
10.3.2 N-grams preserving word sequence
10.4 Dictionary approach and machine-learning approach and describe the advantages and limitations of each approach.
10.4.1 Dictionary approach limitations in sentiment
10.5 How term frequency-inverse document frequency (TF-IDF) can be used to determine the appropriate weighting of words in a document.
10.5.1 TF-IDF word weighting comparison
10.6 How the Naive Bayes classifier is used to categorize documents.
10.6.1 Naive Bayes document categorization
10.6.2 Naive Bayes posterior probability normalization
10.7 Factors to consider when evaluating NLP models.
11. Generative AI and LLMs
11.1 Generative artificial intelligence taxonomy based on content modalities and modeling algorithms.
11.2 How embeddings are used to represent word vectors and describe their advantages and limitations.
11.3 How word embeddings can be used to compare words.
11.3.1 Using word embeddings to detect unfavorable text
11.4 Differentiate between the two Word2Vec architectures.
11.4.1 Word2Vec architectures for predicting missing words
11.5 Differentiate between recurrent neural networks (RNNs), LSTM, and transformers for capturing the relationships between words in a sentence.
11.6 The basic structure of LLMs and how they are trained at a conceptual level.
11.6.1 LLM training pipeline stages and conceptual structure
11.6.2 Conceptual overview of LLM training process
11.7 Prompt engineering in the context of LLMs.
11.7.1 Prompt engineering best practices for analysts
11.8 The impact of context length and statelessness on LLM performance and user interaction.
11.8.1 Context length and statelessness in credit underwriting
11.9 How Temperature, Top-K, and Top-P parameters affect the LLM creativity, predictability, and quality of outputs.
11.9.1 Tuning temperature, Top-K, and Top-P parameters
11.10 The challenges in evaluating the performance of GenAI and LLMs and describe different methods to evaluate the outputs.
11.10.1 Ethical frameworks in GenAI output evaluation
11.11 Differentiate between Agentic AI and Generative AI.
11.11.1 Comparing traditional ML, generative AI, and agentic AI
11.12 The applications of GenAI and LLMs.
11.12.1 Applications of LLMs in loan approval decisions
12. Risks and Risk Factors
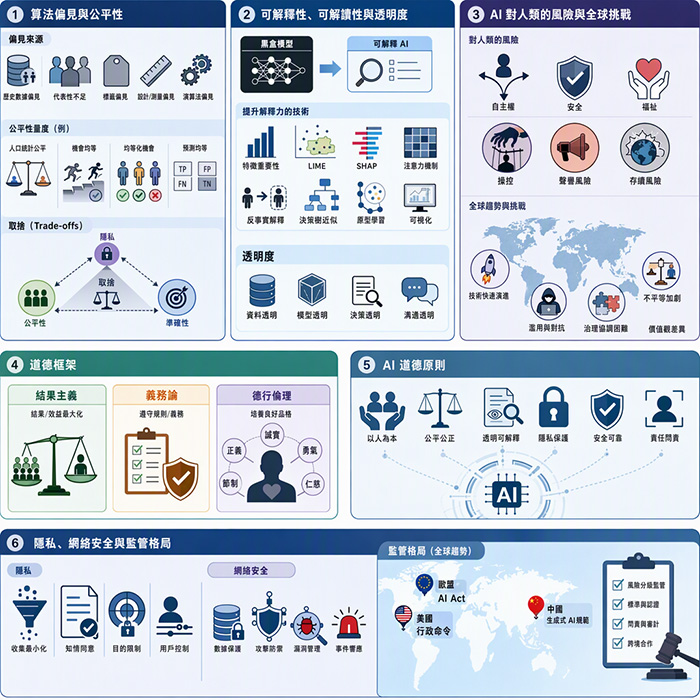
12.1 Describe and differentiate between the concepts of individual and group fairness.
12.1.1 Impartiality as individual versus group fairness
12.1.2 Equal treatment and individual fairness
12.2 Various measures of group fairness.
12.2.1 Sensitivity as a group fairness measure
12.2.2 Assessing group fairness across demographics
12.2.3 Demographic parity as fairness metric
12.3 Trade-offs associated with different concepts and measures of fairness.
12.3.1 Proxy targets and deeper fairness trade-offs
12.3.2 Accuracy-fairness trade-offs in hiring models
12.3.3 Dynamic pricing fairness and ethical trade-offs
12.4 Sources of algorithmic bias and unfairness.
12.4.1 Historical lending bias in training data
12.4.2 Geographic proxy variables causing disparate impact
12.4.3 Proxy features and past hiring decisions
12.4.4 Unequal access bias in healthcare data
12.4.5 Underrepresentation bias in rural training data
12.5 Explainability, interpretability, and transparency.
12.5.1 Distinguishing explainability from interpretability
12.6 Techniques for making AI algorithms more explainable.
12.6.1 Feature attribution and marginal input effects
12.6.2 Local surrogate models for interpretability
12.7 Risks posed by AI to human autonomy, safety, and wellbeing.
12.7.1 Over-reliance risks to human autonomy and safety
12.7.2 Autonomy violations in AI treatment recommendations
12.8 Sources of AI-related reputational risk and strategies for mitigating those risks.
12.8.1 Mitigating reputational risk from biased hiring AI
12.8.2 Explaining loan rejections to mitigate reputational risk
12.9 Global challenges and risks associated with AI.
12.9.1 Worker displacement as global AI risk
12.10 Risks specifically posed by the use of GenAI and possible solutions to address them.
12.10.1 GenAI hallucination and fabricated citations
12.10.2 Governance challenges of generative AI models
12.10.3 GenAI legal and compliance risks
12.10.4 Data leakage risks with third-party GenAI
12.10.5 GenAI governance challenges in banking
12.10.6 Hallucinated covenant breaches in credit memos
13. Responsible and Ethical AI
13.1 Potential benefits of implementing a practical ethics framework.
13.1.1 Defining practical ethics in AI
13.1.2 Benefits of adopting practical ethics
13.1.3 Practical ethics framework accuracy and use
13.2 Compare and contrast consequentialism, deontology, and virtue ethics.
13.2.1 Virtue ethics framework characteristics
13.2.2 Practical wisdom within virtue ethics
13.3 The principles of nonmaleficence, beneficence, justice, autonomy, and explainability.
13.3.1 Justice in allocating scarce treatment
13.4 Sources of and strategies to address algorithmic bias and unfairness.
13.5 Important ethical principles related to privacy.
13.5.1 Consent and purpose limitation in privacy
13.5.2 Data minimization and retention limits
13.5.3 Privacy principle of data deletion
13.5.4 Purpose limitation and data use restriction
13.5.5 Opaque data collection without user knowledge
13.6 The current regulatory landscape and governance challenges associated with AI.
13.6.1 Current data protection regulatory landscape
13.6.2 Cross-regional AI governance challenges
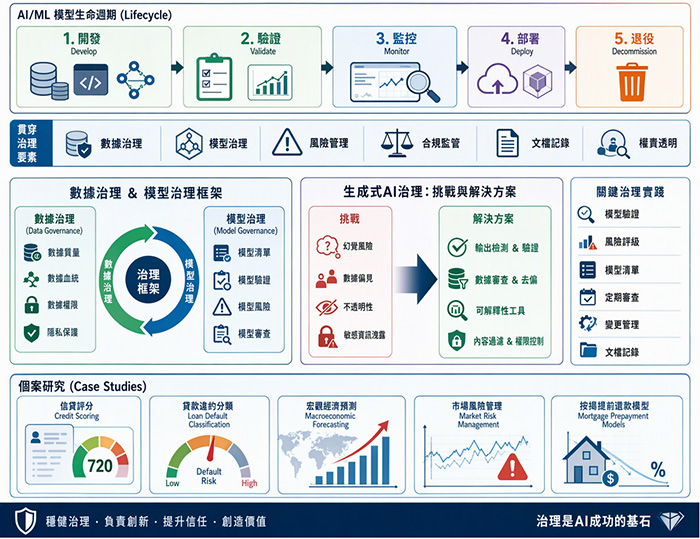
14. Data and AI Model Governance
14.1 Elements of a data governance framework.
14.1.1 Board role in data governance
14.1.2 Data quality and integrity management
14.2 Elements of a model governance framework.
14.3 Steps in the model development and testing process.
14.3.1 White box versus black box testing
14.3.2 Unit testing of model code
14.4 Model validation and its importance.
14.4.1 Ongoing validation of AI models
14.4.2 Importance of model validation
14.5 Policies and procedures related to model governance.
14.5.1 Model governance policy components
14.5.2 Review frequency by risk rating
14.6 Factors to be considered when registering AI/ML applications in a model inventory.
14.6.1 AI and ML model inventory
14.6.2 Registering models in inventory
14.7 Roles and responsibilities associated with model risk management.
14.7.1 Ownership of model risk appetite
14.7.2 MRM framework roles and responsibilities
14.7.3 Model owner responsibilities
14.8 How the model review framework differs for AI/ML models.
14.8.1 AI model review framework differences
14.9 The steps involved in model implementation and adaptation.
14.9.1 Model implementation and adaptation practices
14.10 Potential sources of misinterpretation of model results.
14.10.1 Aggregation bias in model results
14.10.2 Automation bias in AI outputs
14.10.3 Prompt sensitivity and misinterpretation
14.10.4 Proxy variables in deep learning
14.11 Governance challenges related to GenAI and possible solutions to address them.
14.11.1 Power asymmetries in AI governance
|









 繳付學費,過程簡便!